Updated November 2026: We have restructured this beginner’s guide to the Kafka basics, corrected how consumers, ordering and retention work, and updated it for Apache Kafka 4.x and KRaft.
blog by OSO

Master Apache Kafka 101

Updated November 2026: We have restructured this beginner’s guide to the Kafka basics, corrected how consumers, ordering and retention work, and updated it for Apache Kafka 4.x and KRaft.
Apache Kafka is an open source, distributed system for event streaming and stream processing, maintained by the Apache Software Foundation. It was originally built at LinkedIn to handle large volumes of data with high throughput and fault tolerance, and became an Apache project in 2011.
Kafka delivers low latency and high fault tolerance, which is why companies such as Netflix, Uber, Airbnb and The New York Times use it for real-time data streams, stream processing and data integration.
In a nutshell, a Kafka cluster is a group of servers, called brokers, that communicate over a high-performance TCP network protocol. Producers publish events to topics on the brokers, the brokers store them in partitions, and consumers subscribe to topics and read the events.
Kafka uses a publish-subscribe (pub-sub) model. Producers publish messages to topics, and consumers subscribe to the topics they are interested in. Producers don’t need to know about consumers and vice versa, which decouples applications and makes the system easier to scale. This decoupling is the foundation of event-driven architecture.
Kafka consumers pull data: each consumer polls the brokers for new records from the partitions it is assigned, starting from its last committed offset. Because the brokers keep the data on disk and replicate it, a consumer that restarts, or moves to another machine, can carry on from where it left off.
Kafka is built on the distributed commit log, often just called the log. A log is an ordered, append-only sequence of records: new records are added to the end, and each record gets the next offset in its partition.
| Log property | What it means |
|---|---|
| Append-only | Records are only ever added to the end; existing records are never modified |
| Ordered | Each record has an offset, and offsets increase by one within a partition |
| Timestamped | Every record has a timestamp; if the producer doesn’t set one, Kafka adds it |
| Retained | Records stay for the retention period (7 days by default) or until a size limit, whether or not they have been read |
| Compactable | Compacted topics keep only the latest record for each key instead of deleting by age |
Records are immutable, but they are not stored forever: Kafka deletes old log segments when the retention limit passes, or compacts them on compacted topics. Figure 1 shows how offsets work once you have read about producers and consumers.
Producers are the client applications that write records to Kafka topics.
Consumers are the client applications that read records from Kafka topics.

A topic is a named stream of related records, a little like a table in a database or a folder of files.
Partitions are how Kafka scales a topic. Each partition is an ordered log stored on a broker, and a topic’s partitions are spread across the brokers in the cluster.
In figure 2, one producer writes to different partitions of the same topic. Notice that the offsets differ between partitions: each partition keeps its own sequence, and spreading the records across partitions lets the cluster handle more load.

Kafka guarantees order within a partition, not across partitions. If records for the same entity must stay in order, give them the same key so they land in the same partition.
The producer’s partitioner chooses a partition for every record:
| Record | Default behaviour |
|---|---|
| Has a key | The key is hashed, so records with the same key always go to the same partition and stay in order |
| Has no key | The producer fills a batch for one partition, then moves to another (“sticky” partitioning), spreading load evenly over time |
| Explicit partition | The producer writes to the partition you name |
You can also write a custom partitioner, for example to send every “Bike” product to the same partition. Older Kafka clients used round-robin for records without a key; current clients use sticky partitioning because it produces fuller batches.
No. Kafka has no locking between producers. Several producers can write to the same topic and partition at the same time, and the broker appends their batches in the order it receives them.
A Kafka cluster is one or more servers working together.
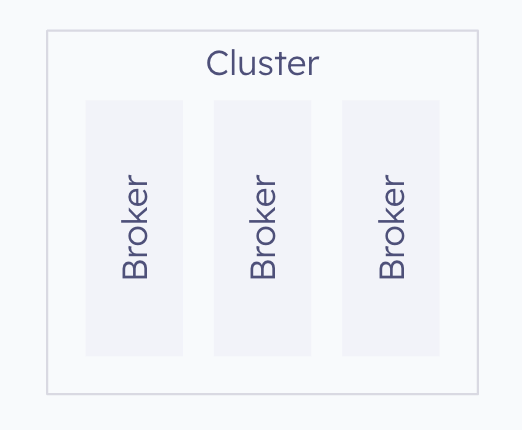
Each server in a Kafka cluster is called a broker.
The controller manages the cluster’s metadata: which brokers are alive, which topics and partitions exist, and which broker leads each partition. When a broker fails, the controller elects new partition leaders.
In current Kafka, the controller is a small quorum of controller nodes running KRaft, Kafka’s built-in Raft consensus protocol. One controller is active at a time and the others are hot standbys. Kafka 4.0 removed ZooKeeper completely, so new clusters always use KRaft. Read more in our guide to running Kafka without ZooKeeper.
Apache Kafka is a distributed, fault-tolerant, low-latency event streaming platform used by companies such as Netflix, Uber, Airbnb and The New York Times. Its publish-subscribe model decouples producers from consumers, its distributed commit log keeps data ordered and durable, and partitioning lets it scale horizontally.
Next, read the official Apache Kafka documentation, our Apache Kafka glossary, our guide to what Apache Kafka is and getting started with Apache Kafka on Azure. To see Kafka in a real project, read how Dufry built the case for a Kafka architecture with a proof of concept.
Key takeaway: Kafka basics come down to a few ideas: producers append events to topics, topics are split into ordered, replicated partitions across a cluster of brokers, and consumers pull events at their own pace by tracking offsets. Order is guaranteed per partition, data is kept for a retention period rather than deleted on read, and KRaft controllers manage the cluster in Kafka 4.x.
Kafka is used to move and process streams of events in real time: activity tracking, log and metrics pipelines, event-driven microservices, change data capture from databases and feeding data into analytics and AI systems.
No. Kafka keeps records for the topic’s retention period, 7 days by default, or until a size limit is reached, whether or not anyone has read them. Compacted topics keep the latest record for each key instead.
Only within a partition. Records in one partition are read in the order they were written, but there is no order across partitions. Give related records the same key to keep them in one partition.
A topic is a named stream of related records. A partition is one ordered, append-only log within a topic. Splitting a topic into partitions lets Kafka spread it across brokers and consumers.
No. Kafka 4.0 removed ZooKeeper. Clusters now use KRaft, where a quorum of Kafka controller nodes manages metadata with the Raft consensus protocol.


Talk to OSO's Kafka engineers about designing your first topics and partitions, running a proof of concept, and taking Kafka safely into production.
CONTACT US