Self-hosted Apache Kafka deployments with a self-service wrapper are a great way to enable an outstanding developer experience. With the rise of the Kubernetes operator pattern it is now relatively straightforward to create this Kafka as a Service offering inside your company, and GitOps is the best way to run that self-service platform. Those two sentences are a concise summary of the key ideas of this guide.
In the last few years, the role of a developer has changed dramatically. The “benevolent dictator for life” of any given codebase is being replaced with a team of developers who have to collaborate on a codebase and integrate countless data sources in real time to move it forward. Instead of the traditional single developer who owns the ETL codebase making all the decisions, creating a bottleneck on data decisions, a group of developers now works together to make a real-time data product.
In this situation, developer experience is of utmost importance as developers collaborate around data-hungry, interconnected platforms. The way to foster an outstanding developer experience of Kafka is to leverage the internal platform approach. An internal platform helps to get event-driven best practices to developers on demand and in a secure way.
Adopting the platform approach alone is not enough. Organisations need to think strategically about how they would go about building and maintaining the Kafka deployments, and how they would build a new development culture around Kafka that makes software delivery seamless.
In this guide, we look at how a self-service data platform delivers an outstanding developer experience, and how GitOps is the way to build and deploy Kafka at scale. With these strategic initiatives in place, software delivery teams can release software continuously and access data in real time, with full confidence in the reliability of the system.
Why does a self-service developer experience matter for Kafka?
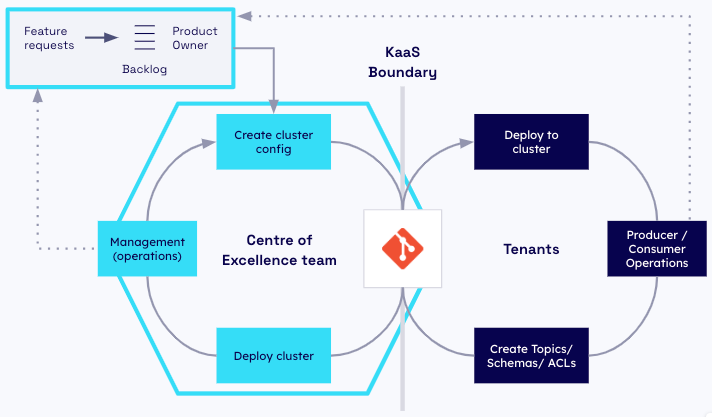
Historically the way a developer could get access to a Kafka broker, topics or data was to ask a system administrator. In the modern era, however, developers require on-demand access to a variety of tools and data sources that enable them to be more productive and deliver increased value from company data in real time. Being able to spin up Kafka clusters on which developers can build, test and ship applications quickly is what makes up the developer experience. An example of the target operating model is shown below:
A lot of companies are still struggling to provide a good developer experience around Kafka that will improve developer productivity and wider adoption of event-driven applications. But it’s not just about providing access to bigger clusters. It’s about providing a better way to access these clusters and resources that removes obstacles and allows self-service. Developers should not have to file a list of support tickets and wait forever for a new Kafka cluster to be deployed.
It’s a good idea to have a consistent process in place, but it’s even better to have a consistent experience for your developers, especially if your organisation has numerous different teams, each with its own set of use cases being built on top of Apache Kafka.
What did the 2023 Data Streaming Report find?
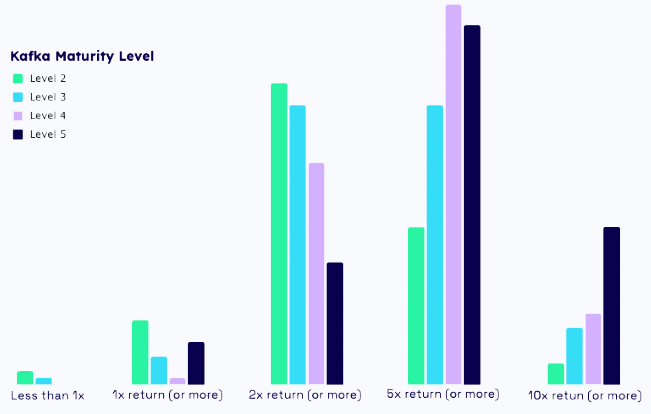
The 2023 Data Streaming Report from Confluent, a survey of 2,250 IT leaders, found that data streaming’s return on investment grows as adoption and the breadth of Kafka use cases become more widespread and integrated.
Key finding
What the report found
Data streaming drives business value and strong return on investment
64% of organisations at Level 2 of the maturity curve are achieving or anticipating 2x-5x returns, rising to 78% at Level 3
Data streaming is a top priority for IT investment
89% of respondents say investments in data streaming are important, with 44% citing it as a top strategic priority
The biggest challenges are silos and skills gaps
74% of IT leaders cite fragmented projects and uncoordinated teams and budgets as a challenge or major hurdle
Who are the application development teams?
The application development teams deliver event-driven applications and data products using Apache Kafka at the core. These teams are aligned according to the organisation’s data strategy. A common approach is for organisations to organise their development teams by product, although in some cases it can be by the data set owners. Application development teams care about moving faster and deploying new features and updates with little or no friction.
What is the Kafka as a Service (KaaS) approach?
While there are many ways to deliver the Apache Kafka platform and its tooling to application developers, the favourite approach of high-performing DevOps teams is to deploy a self-service, prescriptive set of YAML files on Kubernetes that developers use to create and access the Kafka resources they need on their own.
The platform team has a critical mission: to provide the foundational capability to create these Kafka resources and the guardrails that enable application development teams to work effectively when building on top of Apache Kafka. A platform team delivers self-service automation to developers to repeatedly create, update and manage Kafka clusters at scale. The Kafka as a Service (KaaS) offering they build is a collection of self-service automations, tools, knowledge and support enabling Kafka cluster deployment at scale throughout the whole organisation.
A development team should have a high degree of autonomy, but it also relies on the central Kafka platform team to deliver the resources it needs to get its work done. In this way, application development teams are internal customers, known as tenants, of the platform team. To properly fulfil its role as an internal service provider, the Kafka platform team must take a strategic approach to resource management.
Increasing your Kafka adoption curve with KaaS
Why choose a KaaS approach?
The KaaS approach is being adopted by every kind of organisation, from every industry, across every part of the world. Combining a well-defined onboarding process with a documented governance process on the self-service wrapper enables every product team to deploy changes to Kafka in a simple, compliant and repeatable manner.
The job of the KaaS platform team in this case is to enforce compliance while giving more power to developers. There are numerous reasons for adopting a KaaS approach to Apache Kafka delivery. Here are some of the key reasons:
Manage Kafka deployments from on-premise to cloud to edge
Scale Kafka clusters to meet demand
Enable built-in compliance using templated ACLs
Enforce zero-trust security using Open Policy Agent
What are the benefits of the KaaS approach?
Benefit
How the platform delivers it
Example
Manage deployments from on-premise to cloud to edge
One GitOps operating model for every site and cloud
Lloyds Banking Group
Scale clusters to meet demand
Kubernetes operators add broker resources in minutes
Dufry
Built-in compliance with templated ACLs
Teams request read access to topics through the platform
Department for Work and Pensions
Zero-trust security with Open Policy Agent
Policy as code validates every tenant request
Policy checks before resources are applied
A. Manage Kafka deployments from on-premise to cloud to edge
As the infrastructure stack becomes more complex, what organisations need is a consistent way to build and deliver Kafka deployments from on-prem to edge. With the use of the Kafka Connect framework, organisations that need to support legacy applications can leverage Change Data Capture (CDC) in a federated model to capture changes from one deployment to another.
The KaaS platform approach at Lloyds Banking Group in the UK enables thousands of application owners and vendors to securely adopt Kafka and deploy their clusters on-premise, across multiple sites and even across public clouds with the standard GitOps operating model.
With this tremendous infrastructure and data complexity, Lloyds Banking Group relies heavily on the consistency that the KaaS platform approach brings.
B. Scale Kafka clusters to meet demand
Platforms are exceptionally good at making components repeatable and reusable using standard Kubernetes operators. This trait is especially useful when an Apache Kafka cluster needs to be scaled to increase throughput.
Being in the travel retail space, Dufry (renamed Avolta in November 2023 after its combination with Autogrill) sells through physical outlets as well as online and has many days of unusually high traffic spikes. For example, to prepare for a Cyber Monday sale, the platform team had to start provisioning additional Kafka cluster resources (brokers) two to three weeks in advance, and always over-provision. Very short internal deadlines for big product launches, sometimes 30 minutes or less, had the teams struggling to scale up to support a tenfold increase in web traffic. Some of their applications that usually handle around 300 operations per second can shoot up to 3,000 in a matter of minutes.
By leveraging the Kubernetes Kafka operator approach, Dufry was able to adopt a cloud-first approach. This gave them the power of cloud scalability, as they could easily configure new Kafka cluster resources in minutes to meet the surge in demand.
During the proof-of-concept stage, the evaluating product team discovered that they were able to operate a number of Kafka clusters with only three developers. This gave the team the confidence to move away from a traditional VM architecture and build consistent end-to-end workflows that increase consistency and introduce standardisation. Today, Dufry is confident that its Kafka clusters can meet any spike in traffic without a hassle.
C. Enable built-in compliance using templated ACLs
Security comes first for any organisation, particularly an organisation like the Department for Work and Pensions (DWP) in the UK. With the UK’s state pension and benefits system relying on the information the department processes, there is no room for error with security. The DWP has been transforming itself in recent years from a traditional organisation with siloed departments and legacy systems to one founded on open source software and modern cloud-native practices. Along the way, it has kept DevSecOps as its top priority. To make this transformation possible, it leveraged Kafka to connect and integrate modern data pipelines with legacy data.
Security is baked into the KaaS platform at DWP using a templated ACL approach, so developers only need read permission requests to certain topics to be approved to share data with other services in the organisation. Application developers are able to consume data from these topics without ever reaching out to the cyber security people outside their team. This bakes in security from the get-go and allows a security-first mindset even when developers are working with test data.
D. Enforce zero-trust security using Open Policy Agent (OPA)
Implementing a policy engine to block objects that could harm or affect the cluster if they don’t meet the central Kafka requirements is essential in self-service platforms. Using policies enables users to build complex configurations that other tools, such as Terraform or Ansible, cannot achieve.
Open Policy Agent lets you use policy as code to establish Kafka guardrails and enforce built-in compliance. It uses a high-level declarative language called Rego to specify these policies as code, such as validating tenant configuration before it is applied to Kafka clusters. This greatly improves security, as bad actors cannot easily apply or update configuration from their repositories.
The first benefit of using OPA is that you decouple your policies from your infrastructure and Kafka clusters, so the people responsible for policy management can control the policy separately from the tenant requests for Kafka resources. The second benefit is localising violations and conflicts, reducing the risk of human error or misconfiguration affecting other tenants. Policy decisions are not restricted to yes/no or allow/deny answers; this flexibility can be used to validate tenant throughput and topic partition count. Like query inputs, your policies should create structured data as an output which can be reused across tenants. This is what baked-in security looks like in practice.
Why is an internal KaaS platform built, not bought?
A KaaS platform is a complex system of technical and business processes specific to your organisation, and it cannot be bought ready-made from any vendor. It needs to integrate into the operations of your teams and be tailored to the specific needs of each organisation. No two organisations will have the same kind of KaaS platform. Managed Kafka services can run the brokers for you (see our comparison of the best managed Kafka services), but the tenant onboarding, guardrails and workflows on top still have to be designed for your organisation.
There is, however, one common trait that all platforms have. They need to be built using a set of modular building blocks that work across any type of infrastructure and are flexible enough to meet all the varied needs of the business.
One option that has proved to be an elegant and effective solution to platform building is Git. Git is widely used in software delivery, and its success is the reason why platforms like GitHub and GitLab are household names in every software delivery team today. Git has led to the rise of a modern approach to software delivery called GitOps.
How do you build a KaaS platform with GitOps?
GitOps views Git as the single source of truth. The entire system needs to be declared in Git and any changes are initiated using a simple pull request. With the introduction of the Confluent for Kubernetes (CFK) and Strimzi operators, it is now possible to declaratively define your entire Kafka cluster and all its resources in YAML.
GitOps allows you to create and manage your entire Kafka platform through Git and treat your Kafka resources as you would your source code. Every change and broker configuration is made through a pull request, everyone has access to the repository, and changes can be rolled back if needed. Just like with your code, you should trust the platform you are building on. With GitOps, you can make sure that each configuration change is verified by your peers and automatically tested before it is deployed.
Your KaaS platform should not be managed by one single person. It’s a bad idea to have one person who deploys changes without anyone else knowing about it. GitOps allows you to have a team of people who are responsible for each change being made on the platform as a whole. Beyond this, it helps to build a platform that is modular, flexible and, importantly, secure.
GitOps for KaaS platform building
GitOps is a way to manage Kafka configuration, topics and ACLs from Git repositories. It requires that every part of the Kafka platform be defined in Git, with Git as the single source of truth and all platform configuration stored there.
Using Git, Kafka operations can be automated with ease. Whenever configuration drift occurs, it is immediately spotted and corrected in a controlled manner.
GitOps is great for building internal platforms because it has a set of strong defaults for versioning using Git repositories. The GitOps framework can greatly simplify and speed up the process of building and maintaining internal platforms. It is much easier to manage internal applications when using a strategy like GitOps, because you can share and replicate resources, tools and workflows across various teams from a single platform.
With GitOps, everything about your Kafka cluster (brokers, topics, users, ACLs, schemas) must be declarative, which means deployments are reliable and any action can be replayed or rolled back at any time.
What are the benefits of GitOps for a KaaS platform?
Here are the top benefits of using GitOps to build and manage your Kafka clusters:
Make self-contained, risk-aware decisions
Detect broker configuration and topology drift
Enable built-in compliance
Implement on-demand Kafka clusters
Let’s look at each of these benefits in detail.
A. Make self-contained, risk-aware decisions
Risk awareness in deployments is about being aware of which lines of configuration have changed, and having the ability to roll back specific changes if necessary. This kind of precise control over Kafka clusters and change management is a hallmark of the platform approach to software delivery.
Thanks to GitOps, in conjunction with Kubernetes Kafka operators, the central KaaS team can now roll out changes to multiple clusters at once with almost no downtime. Before GitOps, it was the norm for teams to experience outages during a broker upgrade. Now, instead of outages, we have automatic rollbacks, with the operator doing the hard work. In fact, trusting the operator to order the resource creation process is now common practice, something which was a purely manual sequence a couple of years ago.
B. Detect broker configuration and topology drift
Drift of any sort plagues distributed teams. Especially as the Kafka cluster becomes larger, drift leads to incompatibility, performance issues and even outages in parts of the application stack. GitOps counters this challenge by embracing a declarative approach to building and configuring Kafka clusters. This ensures that the clusters, topics, users and ACLs always stay faithful to the declared state in Git.
GitOps effectively reduces your attack surface by not allowing people to make manual changes to production: changes can only be applied through a reviewed change in Git. In the cluster, in the infrastructure and in your data governance rules, you do everything in Git. Drift detection doesn’t just make Kafka clusters easier to run and more predictable; it greatly tightens security controls.
C. Enable built-in compliance
For organisations in highly regulated industries like financial services and healthcare, compliance is a high priority. They have specific needs to keep data on-premises and to ensure a complete audit trail of all actions performed within the system. With these high expectations, “ClickOps” or ad hoc changes will not hold up. Instead, only a battle-tested platform approach with full delivery pipeline automation can deliver the peace of mind required.
Lloyds Banking Group, the UK’s largest bank by customer accounts, faced the challenge that every Kafka cluster it deployed had to meet a unique mix of regulatory, security and data governance requirements. The central KaaS platform team wanted the scalability and reliability of adopting Kubernetes, and also sought to leverage the ecosystem of cloud-native open source projects like Argo CD and Flux CD to improve its time to value.
Lloyds Banking Group defined a Kafka resource naming standard, enforced with a combination of OPA policy and Argo Events. Automating these governance rules and managing them with GitOps gave the SREs a way to validate new topics through a pull request. The result is a repeatable, scalable platform that spans environments with security guardrails specific to the underlying Kafka cluster. For example, topic replication factor in a development environment will be different from production because of resilience requirements.
D. Implement on-demand Kafka clusters
With the introduction of ApplicationSet in the Argo CD project, specifically the Git generator, Kafka clusters can now be provisioned from a new branch, directory or pull request using a GitOps workflow. These are essentially ephemeral environments, which are removed after a testing cycle or once a feature branch has been tested and merged. In traditional testing workflows, you may have deployed your changes to a shared development Kafka cluster, waited for QA to validate your changes and received feedback. Time was wasted between teams on environment coordination or test data to validate the new changes.
With the combination of ApplicationSet templating and ephemeral environments, you can quickly spin up a test Kafka cluster based on the changes in your feature branch. This means the QA or UX team can suggest improvements during the code review process without affecting any other team consuming Kafka.
How do you adopt Kafka as a Service?
The time it takes for your organisation to adopt Kafka as a Service greatly depends on where you are in your Kafka maturity journey. If you’ve already been leveraging Git for collaboration, have a CI/CD pipeline in place and use open source tooling across your pipeline, you may see a quicker adoption time. However, for many organisations, it can take more time.
OSO recommends a four-step, phased approach when adopting Kafka as a Service through GitOps:
Identify a developer advocate or team who is happy to act as the early adopters.
Build an MVP with a clearly defined set of functional and operational requirements.
Gather feedback from your tenants and iterate on feature requests.
Onboard more tenants as platform maturity and trust in the stack increase.
This phased approach gives the various teams adequate time to get on board at their own pace. It also gives the KaaS platform team time to adapt to issues as they arise, ensuring smoother Kafka adoption.
Describe everything as code
Even for organisations that have been deploying Kafka clusters over multiple environments for a while, the concept of “everything as code” can be a stretch. Often many changes are made ad hoc, yet everything as code is essential for GitOps and for a platform model. To build declarative systems, every part of the system first needs to be defined before it can be declared. This is why it is important to take the time to move the entire system from various disparate pieces into Git.
Use the CFK or Strimzi operator with Flux or Argo CD for a proof of concept
KaaS is powered by a combination of tools that are backed by large developer communities. Flux and Argo CD are two key open source tools that make up the GitOps toolchain. The Kafka operators each have their own benefits and drawbacks, so evaluate them (outside the scope of this guide) before choosing one over the other.
Key takeaways
To summarise, here are the key points to take away to start building a Kafka as a Service capability in your organisation:
Developer experience matters: development teams today need a self-service developer experience (DX) to consume Kafka for their specific use case.
Use the Kafka as a Service platform approach: top-performing, data-driven organisations find the KaaS platform approach the most effective way to share data products across business units. It lets you manage deployments from on-premise to cloud to edge, scale infrastructure to meet demand, build in compliance with templated ACLs and enforce zero-trust security with Open Policy Agent.
Use GitOps for KaaS platform building: GitOps is flexible yet secure. It supports self-contained, risk-aware decisions, detects configuration and topology drift, builds in compliance and enables on-demand Kafka clusters.
Follow KaaS adoption best practices: take a phased approach, describe everything as code and run a proof of concept with the CFK or Strimzi operator and Flux or Argo CD.
Engage experts: OSO’s enterprise experience can simplify and speed up Kafka adoption inside your organisation.
Key takeaway: treat Kafka as an internal product. Give tenants self-service through a Kubernetes operator and GitOps, enforce guardrails with templated ACLs and policy as code, and grow adoption in phases from a single early-adopter team.
OSO: the Kafka experts
OSO is on the journey to becoming the number one Kafka consulting company in Europe.
Our mission is to help teams build event-driven applications on Kafka to enable real-time access to their data and introduce meaningful innovations that drive business growth.
We offer a variety of tailored services and bring industry-leading expertise to support Apache Kafka in your organisation. Our developer-first culture, combined with our cross-industry experience and battle-tested delivery methods, allows us to deliver the most impactful solutions for your business.
The OSO team has worked with digital-native businesses globally to build best-in-class, sector-specific solutions, and has partnered with the world’s leading technology companies to help businesses implement Kafka at scale.
Since being formed, we have worked with a number of well-established clients on these initiatives, including Lloyds Banking Group, HSBC, Fortescue Metals Group, HS2, M1 Finance and Dufry.
Kafka as a Service is an internal self-service platform that lets application teams create Kafka clusters, topics, users and ACLs on demand. A central platform team provides the automation, guardrails and support, and the application teams use it as internal customers, or tenants.
Is Kafka as a Service the same as managed Kafka?
Not quite. A managed Kafka service, such as Confluent Cloud or Amazon MSK, runs the brokers for you. An internal Kafka as a Service platform is the self-service layer of onboarding, guardrails and workflows that your platform team builds, and it can sit on self-managed or managed Kafka.
Which tools are used to build a Kafka as a Service platform?
A typical stack is Kubernetes with a Kafka operator such as Strimzi or Confluent for Kubernetes, a GitOps tool such as Flux or Argo CD to apply changes from Git, and Open Policy Agent to validate tenant requests as policy as code before they reach the cluster.
How does GitOps help manage Kafka?
GitOps keeps every broker setting, topic, user and ACL as declarative configuration in Git. Changes go through reviewed pull requests, drift from the declared state is detected and corrected, and any change can be rolled back, which gives an audit trail for compliance.
How long does it take to adopt Kafka as a Service?
It depends on your maturity. Teams that already use Git, CI/CD and open source tooling adopt it faster. OSO recommends a phased approach: start with an early-adopter team, build an MVP, iterate on tenant feedback and onboard more tenants as trust grows.